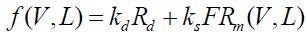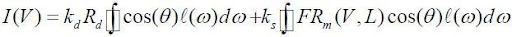Thursday, May 13, 2010

Silverlight on Windows 7 Phone – Performance Tuning

Recently, I have been reviewing some of the content from MIX10, specifically pertaining to the talks on the new Windows Phone.  I came upon the talk from Seema Ramchandani (http://live.visitmix.com/MIX10/Sessions/CL60).  This was full of good tips on performance tools and tuning for Silverlight on the phone.  I wanted to share the items that stood out to me.

First, the idea of having a UI thread (that uses the phone CPU) and a Render thread (that runs on the GPU) is key to making a smooth rich interface.  The UI thread should be reserved for input primarily with the animations and other calculations being done on the render thread.

UI Virtualization-

For instance the listbox shows by default (styles) 6 rows.  What is hidden is that the 5 above and 5 below are also in the visual tree.  These are not recreated as the ui is scrolled but simply reused.

The Loop of all Loops (render loop)

A timer in triggers the render loop every 33 milliseconds and attempts to draw.  First we check for property changes (ie. movement).  Then the visual tree is recurred 2 times.  First to see “how big” everything is.  Then on the second pass arranging the items to be rendered is performed (and clipping).  Next we queue up the rendering changes.  Only one back buffer is rasterized per frame.  And then the buffer is rendered.

Tools

  • Enable frame rate counter (in main)
  • Enable redraw regions (to see what is being redrawn in different colors)

We should only be drawing the changes, and the redraw regions flag will show you what this is.  Lots of colors is bad :).

Threads

  • Render thread
  • UI thread
  • Child threads
      • Rasterization
      • Media Decoding


  • Less is more – keep the app lean for best performance (goes without saying)
  • Limit activity on UI thread
  • Leverage render thread
  • Leverage GPU
  • Debug, Debug, Debug

Active input on the device can take 15-25% of the device CPU!  Thus, we need the render thread to keep the application responding real time.

Quick way to check if we are using the GPU.  Enable the frame rate counter.  If this is rendered when you run the application, then the GPU is being used.

Use CacheMode=”Bitmap Cache” to force bitmap caching for GPU optimization.  Certain items will cache automatically (ie. double animations).

Order is important in the xaml to keep the cached bitmaps close together (less textures), which will increase gpu performance.

Media and effects in the same frame == bad!

Max texture size on desktop and phone is 2048 in any direction.

60 fps in the CTP, but will be limited to 30 fps max on release build (to keep battery life as high as possible).

Thursday, January 21, 2010

Global Game Jam

Had a friend mention the Global Game Jam to me today.  I was still able to register for the New York City location.  The event takes place between January 29th and 31st.  The NYC location currently has 66 jammers registered.  I will post updates as this takes place.

Global Game Jam Site

Saturday, May 9, 2009

Project: GPU replacement

Recently, my otherwise perfect XPS laptop experienced a GPU failure.  It was time for me to upgrade my laptop anyway, so I went ahead a got a 1730 to replace this 1710.  I then contacted a Dell reseller in CA for a replacement GPU (these things are $680 from Dell) and was able to secure a new one for $400.  This is Nvidia 7950 GTX, the largest GPU available for the XPS M1710.  I received the new GPU a few days ago and installed today.  It required pretty much stripping the laptop but all is working fine now.  Pics can be found here.  BTW, the 1730 is purchased has dual 8800 GTX (for a grand total of 1GB video memory) with SLI.  It runs well. :)

Thursday, March 26, 2009

The Beauty of Destruction (Pete Isensee, Microsoft)

C++ Destructor Definition

  • One
  • Special
  • Deterministic –> called at well defined times
  • Automatic –> object out of scope or delete
  • Symmetric –> constructor fits
  • Member –> part of a class
  • Function
  • With
    • A special name (~)
    • No parameters
    • No return type
  • Designed to
    • Give last rites
    • Before object death

C# uses finalizer different (called by GC) non-deterministic, same in Java

When destructors are called

  • Global or static object, called when terminates
  • Arrays destructed in reverse way
  • STL container , unspecified order
  • delete operator
  • out of scope
  • temp objects
  • exception thrown (stack unwinding)
  • explicitly
  • exit()
  • abort (does not call destructor)

Order of destruction

  • Rule of thumb: Reverse order of construction
  • Specifically
    • Destructor body
    • Data members in reverse order of declaration
    • Direct non-virtual base classes in reverse order
    • Virtual base classes in reverse order

Implicit Destructors

  • not specified by programmer
  • inline by default
  • public
  • recommended for struct-like POD-only objects
  • for everything else, avoid implicit destructors
    • better debugging
    • improved perf analysis

Trivial Destructors

  • Implicit
  • Not virtual
  • All direct base classes have trivial dtors
  • All non-static members have trivial dtors
  • Destructors that never do anything

Virtual Destructors

  • Guarantee that derived classes get cleaned up
  • Rule of thumb: if class has virtual functions, dtor should be virtual
    • if delete on Base* could ever point to a Derived*
  • Perf: Obj with any virtual funcs includes a vtable ptr
  • Idiom exceptions: mixin classes
  • Pure signals abstract class (virtual ~T() = 0{})

Partial Construction & Destruction

  • Dtors are only called for fully constructed objects
  • if a ctor throws, obj was not fully constructed
    • obj dtor will not be called
    • but fully constructed subobjects will be destroyed
  • Always use RAII with ctors
    • Resource Acquisition Is Initialization

Virtual Functions in Destructors

  • Virtual functions are not virtual inside dtors

C++ Exception Handling

  • Destructors : Exceptions :: Spock : Kirk
  • Wrap any function that acquires a resource in a class where dtor releases the resource
  • Never allow an exception to exit a dtor
    • Best: don’t throw in dtor
    • OK: wrap throwing code in a try/catch
  • Good advice even if you don’t use C++EH

Multithreading

  • You are responsible for protecting objects and their contents
  • Sharing an object across threads
    • Use shared_ptr
    • or some other reference counting
    • or otherwise ensure only one thread can destroy
  • Protect shared memory (global counters, ref counts) in dtor

delete and Destructors

  • delete p is a two-step process

Explicit Destructors

  • Destructors can be called directly
  • Avoid 99.9% of the time
  • Very powerful for custom memory scenarios
  • Examples
    • w / placement new
    • STL allocators

std::allocator

  • Allocators enable custom STL container memory
  • Two key destructive functions

shared_ptr

  • Templated non-intrusive deterministically referenced-counted smart pointer

shared_ptr deleters

  • Deleter : a functor called on the stored raw pointer when ref count hits zero

Performance

  • Destructors are called a LOT
  • they are invisible in code
  • streamline common dtors
  • the best dtor is empty
  • inlining
  • profile

The Rendering Technology of KillZone 2 (Michal Valient)

How we made Killzone 2 run @ 30FPS

  • Deferred shading
  • Diet for render targets
  • Dirty lighting tricks
  • Rendering, memory and SPUs

Deferred shading

  • not forward rendering
  • Geometry pass – fill the GBuffer (all material info for lighting)
  • loading depth map, normal / bump map, albedo (diffuse color and texture), shininess (reflective materials)
  • Lighting pass – accumulate info (only light, no textures)

GBuffer

  • RGBA FP16 buffers proved to be too much
  • Moved to RGBA8
    • 4xRGBA8 + D24S8 – 18.4mb
    • 2xMSAA (Quincunx) – 36.8mb
  • Memory reused by later rendering stages
    • Low res pass, post processing, HUD
  • View space position computed from depth buffer
  • Normal.z = sqrt(1 – Normal.x2 – Normal.y2)
    • No neg z, but does not cause problems
    • 2xFP16 compressed to RGBA8 on write
  • Motion vectors – screen space
  • Albedo – material diffuse color
  • Roughness – specular exponent in log range
  • Specular intesity – single channel only
  • Sun Shadow – pre-rendered sun shadows (offline light map)
    • Mixed with real-time sun shadows
  • Lighting accumulation buffer (LAB)
    • Geometry pass fills in indirect lighting terms
      • Stored in lightmaps and IBLs
      • Adds ambient color, scene reflections
    • Lighting pass adds contribution of each light
  • Glow – contains HDR luminance of LAB
    • Used to reconstruct HDR RGB for bloom

Lighting pass

  • Most expensive pass
    • 100+ dynamic lights per frame
    • 10+ shadow casting lights per frame
    • AA means more of everything
  • Optimization
    • Avoid hard work
    • Work less for MSAA
    • Precompute sun shadow offline
    • Approximate

Avoid hard work

  • Don’t run shaders
    • Use early z/stencil cull unit
    • Depth bounds test is the new cool
    • Enable conditional rendering
  • Optimized light shaders
    • For each combination of light features
  • Fade out shadows for small lights
  • Remove small objects from shadow map

Lighting pass and MSAA

  • MSAA facts
    • Each sample has to be lit
    • Samples of non-edge pixel are equal
  • KZ2 solution – in shader supersampling
    • Run at 1280x720 not 2560x720
    • Light two samples in one go

Shadow map filtering distribution

  • Motivation
    • Define filtering quality per pixel rather than per sample.
  • Split filter coordinates into disjoint sets
    • One set per pixel sample
  • MSAA is almost as fast as non-MSAA

Sunlight

  • Fullscreen directional light
  • We divide screen into depth slices
  • Each depth slice is lit separately
    • Different shadow properties
    • Used depth bounds test
  • Use sun shadow from GBuffer
    • Stencil mark pixels completely in shadow
      • Skip expensive sunlight shader
    • Also mixed with real-time shadows

Sunlight rendering – Fake MSAA

  • Used only in distance pixels
  • Cut down lighting cost
    • Run lighting equation on closest sample only
  • Is this wrong?
    • Its a hack
    • Works correctly against background
    • The edges are still partially anti-aliased
    • Distant scenery is heavily post processed

Sunlight – shadow map rendering

  • Generate shadow map for each depth slice
  • Common approach
    • Align shadow map to view direction
    • Pros – max shadow map usage
    • Result – shadow map shimmering
  • Fix
      • Remove shadow map rotation
        • Align shadow maps to world instead of view
        • Remove sub-pixel movement
        • Cons – unused shadow map space

GPU driven memory allocation system

Push Buffer building

  • Multiple SPUs building PB in parallel
  • Additional SPUs generating data
    • Skinning, particles – VB
    • IBL interpolation – textures
  • Common solutions
    • Ring Buffering
      • Issue with out of order allocations
    • Double Buffering
      • Too much memory

KZ2 render memory allocator

  • Fixed mem pool
    • 22MB block – split into 256k blocks
  • Each block has associated AllocationID
    • Specified by client during allocation
    • Only whole block can be allocated
  • Global FreeID identify free blocks
    • Updated as RSX consumes ‘Free’ marker
  • Lockless, out of order, memory allocation
    • From PPU and/or SPU
    • Simple table walk (fast!)
  • Allows immediate memory reuse
    • WE generate push-buffer just in time for RSX
    • Block can be reused right after RSX consumption
  • Can allocate memory for skinning early…
    • and still free at correct point in frame

Direct3D 11 Tessellation Deep Dive (presented by Matt Lee)

High fidelity characters seem a bit out of reach of real-time apps (games).

10 to 30K chars not out of reach for 360/PS3

Striving for Cinematic Quality Characters

think in terms of triangles currently


Catmull-Clark subdivision surfaces

  • Industry standard subdivision surface scheme

Modern implementations don’t require too smooth


Direct3D11

  • Realtime rendering of Catmull-Clark
  • 3 new pipelline stages
  • Hardware design removes bandwidth bottlenecks from current implmentations
  • Better use of multi-core processors and improved shader management

(dynamic shader linking)


Direct3D11 Pipeline

  • Hull Shader
  • Tesselator
  • Domain Shader

Tessleation Data Flow

  • Hull shader – executed per patch
  • Tessellator – executed per patch (fixed-function) generates triangle
  • Domain shader – per tessllated vertex

Hull Shader

  • patch control points (input)
  • output to Domain Shader
  • two phases per patch(control points, patch constant)
  • patch constant output to tessellator (modifies behavior of tessellator)
  • control points go to domain shader

Tessellator

  • state from D3D API
  • input from Patch constant phase
  • generates tessellated triangles
  • out to later stages

Domain Shader

  • Hull Shader and Tessellator output
  • Smooth surface evaluated
  • one vertex
  • Control points are in GPU (saves bandwidth)

Where to use

  • LOD of terrain
  • Bezier patches from higher-order surfaces (Catmull-Clark)

Catmull-Clark

  • Baked into content early
  • Goal is real time
  • Disadvantage (have to build offline and huge memory issues)

Loop-Schaefer approximation (D3D11), others exist

Benefits

  • Content creation easier
  • Save memory
  • Easier LOD (doesn’t require sep meshes) so no use for MIP maps?

Pipeline

  • offline Load control mesh
  • offline compute adjacency for each quad
  • offline compute texture tangent space for each vertex
  • rt Morph & skin the quad mesh in the VS
  • rt convert quad mesh into patches in hull shader
  • rt Evaluate patches using domain shader
  • rt apply displayment map

tangent patches (fixes up surface normals) extrodianry vertex (<4 or > 4)

Available in March 2009 DX SDK (today), next release in June 09

SubD11 sample

Optimization will be performed when hardware is finalized

Current shader design is not expected to perform well on hardware.

Out of Order: Making In-Order Processors Play Nicely (presented by Allan Murphy)

VMX on the 360 for optimization of vector math

Slower than C counterpart, and out of order (so broken)

Missing out of order logic

  • no instruction reordering
  • no store forward hardware
  • smaller caches, slower memory
  • no l3 cache


  • LHS
  • L2 Miss
  • Expensive, non pipelined instructions
  • Branch mispredict penalty

Load Hit Store

  • Store to memory location, then load, flush the L2 cache
  • Casts, changing register set, aliasing
  • Passing by value, or by reference
  • On Pc, instruction reoder and store / forward hardware

L2 Miss

  • Loading from location, checks cache
  • Cost ~610 cycles to load cache line
  • Hot cold split
  • Reduce in-memory data size
  • Use cache coherent structures

Expensive Instructions

  • non pipelined instructions
  • Stalls hardware threads

Branch Mispredict

  • Mispredicting branch
  • 23-24 cycle delay
  • Know how the compiler implements branches
  • Reduce total branch count for task
  • Refactor calculations to remove branches
  • Unroll

Profiling!!!

360 Tools

  • PIX Cpu instruction trace
  • LibPMCPB counters
  • XbPerfView sampling capture

Other Platforms

  • SN Tuner, vTune

Think laterally

  • Inline functions
  • pass and return in register (_declspec(passinreg)
  • _restrict (complier released from being ultra careful
  • const


Compiler options

  • Inline
  • Prefer speed over size
  • Fast floaging point over precise
  • 360 (/Ou removing div by zero, /Oc runs a second code scheduling pass)
  • Reduce parameter counts
  • Prefer 32, 64, 128 bit parameters
  • Isoloate constants
  • Avoid virtual if feasible

Know you cache architecture

  • Cross core sharing policy (L2 shared, L1 single)
  • Prefetch mech (dcbt, dcbz128)
  • L2 1MB, L1 32Kb
  • Cache line 128 byte

Know your instruction set

  • 360 specific (VMX, slow instructions, fsel, vsel, vcmp*, vrlimi)
  • PS3 (altivec)
  • PC (SSE2-4.1 and friends)

What went wrong

  • Correctness
  • Guessed at 1 perf issue
  • SIMD vs straight float
  • Memory access and L2 usage unchanged
  • Branch behavior exactly the same

Image Analysis

  • Gaussian Mixture Model
  • Profiling showed (86% tiem in pixel cost function)

The PlayStation 3’s SPUs in the Real World (presented by Michiel van der Leeuw)

  • Things they did on the SPU’s (post mordum)
  • What worked and didn’t work
  • Practical advice
  • Food for thought

3 Years ~120 team size with 27 programmers

  • Cinematic
  • Dense
  • Realistic
  • Intense


  • 6 x 3.2 Ghz processor
  • Local mem per SPU
  • Very fast DMA


  • Core Requirements
    • Animation
    • AI
    • Skinning
    • Physics
    • Compression/Decompression
    • etc

Graphics

  • Light probe sampling
  • ~2500 static light probes per level
  • 9x3 Spherical Harmonics in KD-tree
  • sample light, blend 4 closet light probes, rotate in view space,
  • bake lights into level

Particle simulation

  •   250 particle systems per frame
  • 150 drawn
  • 3000 particles updated
  • 200 colision ray cast
  • System grown over time

Refactoered

  • Vertex generation
  • Particle simulation inner loop
  • Initilaization & deletion of particles
  • High-level management / glue

Not done on SPU

  • Updated global scene graph
  • Starting & stopping sounds

Image Post Processing

Effects done on SPU

  • Moiton blur
  • Depth of field
  • Bloom

Spu assist the RSX with post-processing

  • RSX prepares low-rew image buffers
  • RSX triggers interrupt to start SPUs
  • SPUs perform image operations
  • RSX already starts next frame
  • Result in SPU processed by RSX early in next frame
  • Similar to PhyreEngine now

SPUs are compute-bound

  • Bandwidth no issue
  • Code can be optimized

Our trade of: RSX vs SPU time

  • SPUs take longer
  • SPUs look better
  • RSX was the bottleneck

Bloom and Lens Relection

  • 13% on one spu
  • Depth dependnd intensity response curve
  • 7x7 guassian blur
  • Upscaling resulst from deifferent levels
  • Internal Lens Relfection
  • Result buffer

Waypoint cover maps –> depth map

IBL Sampling

SPU cost a lot of dev time

Code is future proof, scales to more cores, supports the items they require.

The future is memory-local and excessively parallel

SPUS are just one of these ‘new architectures’

Optimize for the concept

Keep code portable

Parallelization of code takes time

Treat CPU as cluster

Think in workloads / jobs

Build latency in algorithms

Don’t optimize too early

Lockless Programming in Games (Bruce Dawson, Microsoft)

Current Hardware

  • 360 – 6 hardware threads
  • PS3 – 9 hardware threads
  • Windows – Quad cores not uncommon
  • Point being multi-core is here to stay

Multithreading is mandatory if you want to harness the available power.  If not you are really wasting the advanced features of the hardware.

Multithreaded programming is easy if you don’t share data.  :)  Of course this is not usually an option.

Best way to share data between threads is by using locks.  This is important.  Lockless is not a one-size fits all approach.

Lockless programming typically involves a job queue, using STL queue.  The problem is STL queues not thread safe.  So we have to make them safe. :)

Solution, use critical section to block off the code.

Bad things

  • Acquiring and releasing locks takes time
  • Deadlocks
  • Contention – waiting, holding locks too long
  • Priority inversions – system threads on 360 do this (too often)

Use locks carefully or lockless

  • Safely share data without locks (no deadlocks or priority inversion)
  • Cons
      • Very limited, tricky, generally not portable

sList (singly linked list) InterlockedPushEntrySList

This is NOT a queue!  This is a stack!  Don’t use on 360!!!!!

One writer, one reader (singleton) (works on paper, not in real world)

Read data (cpu to L2), write (cpu to L2)

Writes can happen before getting put in L2 cache

Happens on reads too (second read could come from L1)

read and write can pass each other


Power PC read / writes can pass each other but on x86 only load can pass a store

Reads not passing writes would basically disable L1, huge perf hit

publisher / subscriber model

ExportBarrier – no passing sign (stop sign) HANDLE BOTH reads and writes


Compilers are just as evil, rearrange code (single threaded)

Compiler/CPU reordering barriers needed

_ReadWriteBarrier();   x86

_lwsync();  PowerPC  (both cpu and compiler)

Positioning is crucial (barrier between writes)

write-release semantics is the name

read-acquire semantics is the name

reader needs both read / write


Dekker’s / Peterson’s Algorithm


MemoryBarrier

  • x86 _asm xchange Barrier, eax
  • x64 _FastStorefence()
  • power _sync();


what about volatile

standard volatile…..NO

doesn’t prevent CPU reordering and all variables would need to tagged volatile

VC++ is better, doesn’t prevent hardware reodering on 360

Acts as read-acquire / write-release on x86/x64 and Itanium

atomic <T> in C++0x

Double checked locking – singleton


InterlockedXxx

doesn’t work on 360

its a full barrier on x86/x64/Itanium

InterlockedXxx Acquire/Release are portable (preferred)

Uses

  • Reference counts
  • Setting a flag
  • Publish/Subscribe
  • SLists
  • XMCore on 360
  • Double checked locking

Export, import, full barriers

Prefer to use locks!!!!

use lockless when locks are too costly

http://msdn.microsoft.com/en-us/library/bb310595(VS.85).aspx

Keynote: Discovering new development opportunities (Satoru Iwata, Nintendo)

The day starts out with a packed room, all waiting to hear the keynote to be delivered by Satoru Iwata, President of Nintendo.  With the unquestionable success of the Nintendo products worldwide this talk is to pull back the curtain a bit on some the ideas and methods that have lead to this success.

Iwata started off by presenting the obligatory numbers slides showing how much success both the Wii and DS have shown in recent history.  No one can take that away from them, they have several successful platforms currently.

Iwata then started to discuss, arguably the most important developer at Nintendo, Mr. Miyamoto.  He explained that Miyamoto is one of the main reasons for the continued success.  He explained in somewhat detailed terms, how Miyamoto’s development style has achieved this success.

Mr. Miyamoto first starts with a core concept, as do most software projects.  One of the differences comes from where Miyamoto pulls the new ideas from.  He is fascinated with studying humans and their behaviors, specifically, when they are doing something that makes them happy.  He will draw on this, to come up the concept for the new piece of software that he is attempting to create.  For example, he got a dog for his family, and out of this, was born Nintendogs.

Of course, having a good idea for a game concept, and following this through to release of a successful title are 2 very different things.  This brings up the next key point.  This is Miyamoto’s software development style.  He typically will form a very small team (sometimes even just one developer) and they will work on a prototype, or rather a series of prototypes.  At this stage, the graphics are very crude (boxes).  They will work on this for how ever long this takes to perfect the core concept.   At this stage, no even the president of the company will ask how things are going, or when this will be ready for the next stage.  It should be noted that sometimes at this stage, work will be done, but then shelved.  This could happen for various reasons, but almost always, at least some of this will be used at a later time.

If the prototyping has met Miyamoto’s satisfaction, only at this stage will others be brought in on the game.   This is where the polish comes in (graphics) and such, but the core gameplay is pretty much guaranteed at this point.  This saves from the issue of after spending time on later polish items, a core gameplay elements requires a rewrite.  This almost never happens with this style.

Nintendo also has some unique “playtest” elements to the project.  They do not conduct formal playtests.  Instead, Miyamoto will “kidnap” an employee (non-technical) and have them play the game (with no help).  He then checks to see how it works out.  If they are able to understand a play with no help, the dev team has done their job.  If not, its a failure and will be readjusted.

Next, Iwata unveiled the new Virtual console with larger SD support and options to run from SD.  Also some game demos of future titles were shown.  Also, Rhythm Heaven was introduced, and he gave everyone in attendance a free copy, before this can be bought.

Thursday, January 8, 2009

Indexer example in C#

using System;
namespace Indexer
{
class Program
{
static void Main(string[] args)
{
TestObject obj1 = new TestObject();
TestObject obj2 = new TestObject();

obj1.AddData(new[] { "this", "is", "test", "one", "!?" });
obj2.AddData(new[] { "this", "is", "another", "test", "!" });

// output to check object
OutputObject(obj1, "OBJ1");
OutputObject(obj2, "OBJ2");

obj1[1] = "was";
obj2[1] = "used to be";

// output to check object
OutputObject(obj1, "OBJ1");
OutputObject(obj2, "OBJ2");
}

public static void OutputObject(TestObject obj, string name)
{
for (int i = 0; i < 5; i++)
Console.WriteLine(string.Format("{0}: {1}", name, obj[i]));
}
}

class TestObject
{
private readonly string[] store = new string[5];

public string this[int index]
{
get { return store[index]; }
set { store[index] = value; }
}

public void AddData(string[] objData)
{
for (int i = 0; i < 5; i++)
store[i] = objData[i];
}
}
}

Tuesday, January 6, 2009

Memory alignment

I have heard the discussion of memory alignment, or rather the question about is it really necessary. I can say from a standpoint of any system where you would like to carefully manage memory (for speed or scalability), yes, it matters.

Memory bandwidth can quickly become the bottleneck to a system. If we take, for instance, this case. We have a processor that has a memory width of 32 bits. If we are going to fetch something from memory (say an int, which happens to be 32 bits wide). With this situation, as it is aligned, the processor can fetch the value in one cycle.

Many of the data enumerations in DirectX contain a value at the end named x_FORCE_DWORD with a value of 0x7FFFFFFF. This value is 1111111111111111111111111111111 (31) bits. This will guarantee this enum will be at least 32 bits in size.

Sunday, November 16, 2008

Run it or rip it - UPDATED!

Just another update on the upcoming NXE for Xbox live. This pertains to the ability to rip the games to the HDD, in hopes of faster load times/better in game performance. I have said before that I reserve judgement on whether this is a good thing or not, and I think further revisions may help sway me this way. My argument is, when I have time and want to play some games, I don't want to wait for installs!

NeoGaf has posted this link ( http://www.neogaf.com/forum/showpost.php?p=13630060&postcount=189 ) where they tested Halo 3 with the install and without. This drives my point exactly. When a game is built with ability to adapt to hardware (no HDD or HDD), you get a much better game. There are some cases shown here where the game actually ran slower if you copied to the HDD, because they are already doing some rather intelligent caching.

So thats my rant for the day. Careful what you wish for, and please don't make me wait to play!?!?!

Saturday, November 1, 2008

Run it or rip it!

The upcoming NXE (xbox live dashboard update) will bring with it a feature to rip the game to your hard drive and run off that. This is has been a topic of discussion with a few of my friends because there are some conflicting views. The PS3 camp is saying its great, but they are forced to "install" their games. While this makes the game run faster (eliminates some loading issues that have to be coded special), the downside is the customer is left sitting at basically a file copy screen for minutes before being able to jump into the game.

Lets get to some specifics (with the 360). The 360 has a maximum (best case scenario with a pristine disk) transfer rate of about 12 Mbps. Accessing the same data from HDD would be about 10x the speed. This makes loading the required assets much easier for the programmer. The 360 has only 384 MB of system memory, so there is alot of loading from disk/DVD. To get around this programmers have devised complex caching and prediction algorithms to be sure the user is not stalled. In some cases, companies have chose to load limited assets based on whether the user has a HDD or not, as items are cached there. Note currently no company on the 360 for a retail game loads the entire game there, just individual assets (think cache).

A recent post ( http://www.joystiq.com/2008/10/31/xbox-360-load-time-comparison-dvd-vs-hard-drive/ ) has shown the upside. Quieter system and slightly faster load times. They have shown the transfer rate to be about 1.7GB per minute (so they are seeing about 28 Mbps transfer on a file copy). For an 8GB game this would leave the user sitting (best case) slightly under 5 minutes.

I am not sure this is good thing. What I would like to see if the strategy that Games for Windows uses. This is give the user the option when the put the disk in the first time. To wait or not to wait. If they chose not to wait, load only the require level (lets say for arguments sake 1 GB of data), which would take less than a minute (show some screenshots or something in between ;) ). Then predict the next, lets say level, to be loaded and on idle cycles in the game, copy the files ( of course giving priority to the action rendering and game code if they need the resources). This a lazy loading pattern used in programming for many different types of applications.

I would hope that the hardware engineers are thinking about this for the next gen game consoles to allow the movement of assets from optical to hdd. Ultimately download games would be great, no more copy, but there are costs with this as well. HDDs would have to be much larger (hundreds of GBs or TB) and this is big cost to add to selling a console. Anyway, just my thoughts.

Friday, August 15, 2008

Post Mortem: Advances in Real-Time Rendering Part 1

Global Illumination

The discussion about global illumination was headed by Hao Chen, lead graphics software architect at Bungie.

The idea of using global illumination in real-time applications has become a very important concept in new games.  If the surface does not emit any light (emissive) the formula used to calculate global illumination is listed.
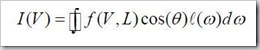
globalillumination


This formula assumes a BRDF (f) has already been calculated.  This presented the Halo3 engineers with 2 challenges.  The first was that while this formula can be solved for a small amount of simple lights (point lights for instance), it is not feasible to solve in real-time as would be needed by the engine.  The second is driven by the fact that Halo contains many different types of surfaces (shiny, dull, etc).  The Phong BRDF model has been used in interactive, real-time environments but again this was only with a small number of point lights.  Also, the engineers did not feel that the Phong model would capture the detail they were looking for.


So the approach taken was to rely on the CookTorrance BRDF model.  The system created could rely on other models, if others were found to be more accurate.
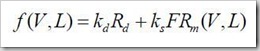

cooktorrance


So the final rendering equation would then be:
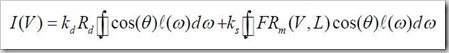

final


There is yet another problem.  The diffuse and specular in the above listed equation involve an integral that is quite expensive to calculate.  If the lights were simple point lights this would probably not be an issue, but as we are using a different type of light source it cannot be used as above.  So the team turned to SH (spherical harmonics).


Specifically, there are 2 cases (diffuse and specular lights).  For diffuse lighting there are shadowed and unshadowed cases that need to be calculated.  Unshadowed diffuse can be calculated in the shader using a quadratic polynomial approximation.  Shadowed diffuse can use pre-computed radiance transfer method result combined (as a dot product) with the incoming light.  There is still one remaining issue to calculate accurate diffuse lighting.  The equation encodes the incident radiance as a single point.  This is not accurate when using to light an entire scene.  Usually, to solve this various random samples are chosen and interpolation used to fill in the rest.  This will give ok results on small areas but not on big scenes.  The other strategy, and one chose here, is to build light maps and grid the scene (and add sample points per cell).  In Halo3, the choice was made to use a photon mapper to "bake" the incident radiance into these light maps.  This is an offline process.


The specular reflectance was much harder to calculate.  The problem is glossy surfaces contain a full range of frequencies.  The choice was made here to break this down to 3 frequencies (low, mid, high).  The high is calculated in the shader (BRDF), the middle frequencies are handled by cube maps, and lows are handled by BRDF again (which is parameterized).


REFERENCES:


[BASRIJACOBS03] BASRI, R., AND JACOBS, D. W. 2003. Lambertian reflectance and
linear subspaces. IEEE Trans. Pattern Anal. Mach. Intell. 25, 2, pp. 218–
233.
[BLINN77] BLINN, J. F. 1977. Models of light reflection for computer synthesized
pictures. ACM SIGGRAPH Comput. Graph. 11, 2, pp. 192–198.
[CHEN08] CHEN, H. Lighting and materials of Halo 3. Game Developers
Conference, 2008.
[COOKTORRANCE81] COOK, R. L., AND TORRANCE, K. E. 1981. A reflectance model
for computer graphics. In Proceedings of ACM SIGGRAPH 1981, pp. 307–
316. [GOODTAYLOR05] GOOD, O., AND TAYLOR, Z. 2005. Optimized photon tracing using
spherical harmonic light maps. In Proceedings of ACM SIGGRAPH 2005,
Technical Sketches, p. 53.
[GSHG98] GREGER, G., SHIRLEY, P., HUBBARD, P. M., AND GREENBERG, D. P. 1998.
The irradiance volume. IEEE Comput. Graph. Appl. 18, 2, pp. 32–43.
[HUWANG08] HU, Y., AND WANG, X. Lightmap compression in Halo 3. Game
Developers Conference, 2008.
[ICG86] IMMEL, D. S., COHEN, M. F., AND GREENBERG, D. P. 1986. A radiosity
method for non-diffuse environments. ACM SIGGRAPH Comput. Graph.
20, 4, pp. 133–142.
[KAJIYA86] KAJIYA, J. T. 1986. The rendering equation. In Proceedings of ACM
SIGGRAPH 1986, pp. 143–150.
[KSS02] KAUTZ, J., SLOAN, P.-P., AND SNYDER, J. 2002. Fast, arbitrary brdf shading
for low-frequency lighting using spherical harmonics. In Proceedings of the
13th Eurographics workshop on Rendering 2002, pp. 291–296.
[NDM05] NGAN, A., DURAND, F., AND MATUSIK, W. 2005. Experimental analysis of
brdf models. In Proceedings of the Eurographics Symposium on Rendering
2005, pp. 117–226.
[OAT05] OAT, C. Irradiance Volumes for Games, Game Developers Conference,
2005. http://ati.amd.com/developer/gdc/GDC2005_PracticalPRT.pdf
[PSS99] PREETHAM, A.J., SHIRLEY, P. AND SMITS, B. 1999. A Practical Analytic
Model for Daylight, In Proceedings of Siggraph 1999, pp. 91 – 100, Los
Angeles, CA.
[RAMAMOORTHIHANRAHAN01] RAMAMOORTHI, R., AND HANRAHAN, P. 2001. An efficient
representation for irradiance environment maps. In Proceedings of ACM
SIGGRAPH 2001, pp. 497–500.
[RAMAMOORTHIHANRAHAN01B] RAMAMOORTHI, R., AND HANRAHAN, P. 2001. On the
relationship between radiance and irradiance: Determining the illumination
from images of a convex Lambertian object. Journal of the Optical Society
of America, Vol. 18, 10, pp. 2448–2459. [RAMAMOORTHIHANRAHAN02] RAMAMOORTHI, R., AND HANRAHAN, P. 2002. Frequency
space environment map rendering. In Proceedings of ACM SIGGRAPH
2002, 517–526.
[SCHLICK94] SCHLICK, C. 1994. An inexpensive BRDF model for physically-based
rendering. Computer Graphics Forums. 13, (3), 233–246.
[SLOANSNYDER02] SLOAN, P.-P., KAUTZ, J., AND SNYDER, J. 2002. Precomputed
radiance transfer for real-time rendering in dynamic, low frequency lighting
environments. ACM Trans. Graph. 21, 3, 527–536.
[SHHS03] SLOAN, P.-P., HALL, J., HART, J., AND SNYDER, J. 2003. Clustered
principal components for precomputed radiance transfer. ACM Trans.
Graph. 22, 3, 382–391.
[VILLEGASSEAN08] VILLEGAS, L., AND SEAN S. Life on the Bungie Farm: Fun Things
to Do with 180 Servers . Game Developers Conference, 2008.

Tuesday, June 17, 2008

Latest reads

Just dropping a line on a book that I am reading.  It is focused on advanced .net debugging techniques and tools.

8650

Friday, May 23, 2008

Something new

I have recently been spending some time learning LUA language.  I am looking into this mainly as this is a standard language used by game developers for in game scripting.  I picked up this book to aid in my studies.  More to follow on this.

Wednesday, April 23, 2008

Elegant Memory Management Ideas

In working on a recent project, involving some callback data in a animation with DirectX and interesting solution to a common problem was presented.  In order to describe the solution correctly, I must setup the scenario.

We have an animation that is loaded from say an X file with the DirectX API.  When using the convenient function to load the X file (D3DXLoadMeshHierarchyFromX) the obvious problem is any callbacks you will require for animation sets will most likely not be stored in the X file.  So we clone the controller/animation sets after the file has been loaded and allocate an array for callback keys/data.

The problem comes in about how to release this memory when complete.  As the data stored here can really be whatever we like, it becomes harder to clean up (as its heap allocated).

The interesting solution that was shown to me was to use COM.  Well, not exactly full COM but the IUknown interface.  Basically we just ensure that our context data object derive from IUknown (and of course implement the required fields).  One of the required methods is Release().  As with all COM objects, memory cleanup revolves around a reference count, and when all references are gone the object remove "itself" from memory.  Also, note we will be required to implement AddRef and QueryInterface as part of derived interface.

Note we are registering a full COM object we are simply using the interface provided by COM as a reference counting mechanism to allow our objects to clean themselves up when it is required.

I thought this was a cool way to use some tried and true COM libraries to solve a very real problem.  :)

Thursday, February 28, 2008

Building a Better Battle : Halo 3 AI

This presentation was given by Damian Isla from Bungie Studios.  It presents the basic architecture and tools used to build the AI system in Halo 3.  This lecture specifically detailed the encounter logic.

Encounters are the "dance".  Basically how the system reacts and collapses in interesting ways.  The "dance" is the illusion of strategic intelligence.  Designers choreograph the "dance" to be interesting and drive the pacing of the story, kinda like a football coach directs his subjects.

Halo 3 uses a 2 stage fallback.  Enemies start off occupying a territory.  The aggressor (player) then pushes them back to fallback point.  After this they are pushed to the last stand location, after which the player will "break" them and finish the battle.  "Spice" is added on top of this by designers to make the encounter play out in a more realistic fashion.

Mission Designers handle the encounter tasks with the AI Engineers handling the squad (how the AI behaves autonomously).

Halo 2 used the Imperative Method to control AI (Finite State Machine).  The designers were given access to dictate what happen as various events were triggered (ie. enemy starts losing battle).  The primary problem with this model was the need for explicit transitions (n^2 complexity).

Halo 3 took a different approach, using the Declarative Method.  This basically works by defining the end result you are looking for (with reference to AI).  You enumerate the "tasks" that are available and let the system make the decision on how to perform these tasks.

One of cool things about using the declarative method is the ability to set relative priorities.  Example would be guard the door but if you can't do this, then hallway.  Also, it brings the notion of hierarchal tasks (sub-tasks).  Example would be guarding the hallway means guarding both ends and middle.

Funny comment that Halo 3 AI works like a Plinko machine.  This means pour tasks into the system, prioritize them, and then pour enemies in and let the system place them and control their behavior.  This also means it's an upside down Plinko machine ;)  This is because tasks can be activated/deactivated at will and cause the enemies performing them to re-evaluate the situation and "do something else".

The system uses a proprietary scripting language named HaloScript.  This allows designers, who are not programmers, to design and use the system.

Thursday, February 21, 2008

Life on the Bungie Farm: Fun Things to Do with 180 servers and 350 processors

This lecture was given by Luis Villegas and Sean Shypula. This was primarily about the server farm and distributed computed system created by Bungie for automated builds of code and content.

Advantages:
  • Faster iterations -> more polished games
  • Keeps complexity under control

Binary Builds (game and tools)

  • Automated tests are run on tool builds only

Lightmap Rendering

  • Pre-Compute Lighting in scenes (Photon Mapping and custom algoritms from Hao and crew)
  • Bakes the level files (output)

Content Builds

  • Compiles assets into monolythic files

Website (bungie.net) Builds

Patches (maintenance items for servers)

Halo 1 -> All assets processed by hand, very few automated tasks

Halo 2 -> More automation (3 servers in farm -> one for each function)

Halo 3 -> Unified systems into single extensible system

The latest iteration, created with Halo 3, did a few new things (rewrite).

  • Unified codebases, implemented single cluster.
  • One farm
  • Updated code to .net (C#), easier to develop/maintain

Stats

  • Over 11,000 builds (exe/dll)
  • Over 9, 000 lightmap builds
  • Over 28,000 other types of builds
  • Halo 3 would not have shipped in current form without the farm.

Interface for users (developers)

  • Had to be easy, simple with "one-button" submit operation
  • Even if users are developers they still don't want to know what is going on behind the scenes

Architecture

  • Single system/multiple workflows
  • Plug in based
  • Workflows divided into client / server plugins (isolation from each other)
  • Server schedules jobs (messages clients)
  • Client start jobs and sent status and results back to server
  • Server manages state of jobs
  • All communications via SQL Server
  • Incremental builds be default
  • Between continuous integration and scheduled (devs run builds ad-hoc and there is a scheduled nightly build)

Symbol Server used (Debugging Tools For Windows)

  • Symbols registered on server

Source Stamping

  • Linker setting for source location
  • Set at compile time
  • Engineers can attach to any client from any client as long as they have Visual Studio installed.

Lightmapper was written specifically for the farm

  • Chunks job parts to clients
  • Merges results

Simple SLB

  • Min / Max configurable
  • More clients used to support workload if clients are mostly idle

Cubemap farms

  • Used XBoxes and PCs for rendering and assembly.
  • Pools of Xbox Dev Kits
  • No client code on Xbox
  • Few changes for Xbox Support

Implementation Details

  • All C# (.Net)
  • Object serialized to XML to start but switch to binary serialization later (speed and mem benefits)
  • Downsides (memory bottlenecks, forced GCs, should have been more careful with memory)